Real-Time Public Transit Routing with Unlimited Transfers
Your phone answers "fastest way across town" in milliseconds — but car routing and transit routing are secretly very different problems. A tour from plain Dijkstra to the ULTRA family, and why timetables make everything harder.
Ask your phone for the fastest way across the city and you get an answer in milliseconds. Behind that tap sits decades of algorithm engineering — and, it turns out, two very different worlds. Routing a car on a road network and routing a passenger through buses and trains look like the same problem, but the tricks that make car routing answer in microseconds quietly fall apart on a timetable.
This post is a tour of the main algorithms in both worlds — from plain old Dijkstra to the state-of-the-art ULTRA family — and why transit is the harder cousin. We'll start with road routing (Dijkstra, A*, Contraction Hierarchies, Bidirectional Dijkstra, Hub Labelling), move on to the core transit algorithms (RAPTOR, CSA, Trip-Based, Transfer Patterns), and finish with what happens once you let people walk as far as they like between stops: multimodal, unlimited-transfer routing.
A quick map of where we're going: road networks have two gifts that make them fast — edge weights that don't change with time, and a natural hierarchy (you leave a side street, hit an arterial, take the motorway, and reverse the pattern at the other end). Transit has neither. That single fact is why most of this post exists.
Road Network Routing
Dijkstra's Algorithm
Dijkstra's algorithm is a one-to-one and one-to-many shortest-path algorithm, which computes shortest paths from a single source in any graph with non-negative edge weights. Each vertex maintains a tentative distance , initialised to except the source at . The algorithm repeatedly settles the unsettled vertex with the smallest tentative distance and relaxes its outgoing edges, updating neighbours if a shorter path is found. Once settled, a vertex is not revisited. There are two flavours: the one-to-many variant runs to completion, settling every reachable vertex, while the one-to-one variant — the one you want for a single trip — stops the moment the target is settled, because its distance is already optimal at that point.
The asymptotic complexity in the classical version of Dijkstra is . This follows from two operations. Extract-min runs times and decrease-key runs up to times, both at cost per call in a binary heap. However, if we replace the standard heap with a Fibonacci one, the cost of the decrease-key operation will be reduced from to . It will lead to a decrease in the asymptotic complexity of Dijkstra search to . However, in practice, Fibonacci heaps win asymptotically only on dense graphs, and they pay for it with large constants and four pointers per node. Engineered routing libraries such as RoutingKit and OSRM avoid them and use a standard heap instead, which is faster on sparse road networks despite the worst-case bound.
In memory, Dijkstra is cheap. It stores a tentative distance from the source to each vertex, a priority queue with at most entries, and a parent pointer per vertex in case we need to reconstruct the path. These are all linear in the number of vertices, so together with the graph itself, stored as an adjacency list, the total is , which dominates when there are more edges than vertices.

A*
Dijkstra has one weakness. Its search is not goal-directed. It spreads out in every direction and ignores where the target is.
A* fixes this. It adds a heuristic that estimates the remaining distance from a vertex to the target . The priority queue is then ordered by , where is the distance from the source. The heuristic pulls the search towards the target.
The heuristic has to be chosen carefully. To keep the result optimal, must be admissible: it never overestimates the real distance to . The graph-search version, which never reopens a settled vertex, also needs to be consistent: for every edge . On road networks the straight-line Euclidean distance works well. If the edge weights are travel times, we divide it by the maximum speed so it stays admissible.
A* is tied to one target. So it answers one-to-one queries only. In a one-to-many setup there is no fixed target, so it gives no benefit. By default it needs no preprocessing. Some heuristics are the exception, such as the landmark-based ALT.

A* reuses the same graph data structure as Dijkstra. It also has the same worst-case asymptotic complexity as Dijkstra. The win is practical, not asymptotic. A good heuristic settles far fewer vertices, so on road networks, A* is usually much faster in practice.
Contraction Hierarchies (CH)
The Contraction Hierarchies algorithm is a precomputation technique motivated by an observation about how roads were built. A journey from one suburb to another typically follows a fixed pattern: leave on a local street, join a larger arterial, merge onto a motorway, exit onto a regional road, and arrive back on local streets. Road networks exhibit a natural hierarchy of importance, and long shortest paths consistently follow this structure.
Sanders and Schultes formalised this as Highway Hierarchies, showing that restricting the search to progressively more important roads yields substantial speedups.

Contraction Hierarchies extend this idea further and automatically calculate the hierarchy from edge weights, without requiring road category labels. Preprocessing assigns each vertex a rank and contracts the vertices one by one in ascending rank order. Contracting a vertex means that we remove it from the graph and add shortcut edges between its higher-ranked neighbours to preserve all shortest-path distances. A shortcut is added only when no path of equal or lesser cost exists through already-contracted vertices (witness path). The procedure that looks for such a path is called the witness search.
The primary metric for calculating a vertex rank is the edge difference. It is equal to shortcuts added minus edges removed when contracting a vertex. Contracting low-degree vertices first keeps the graph sparse and maintains the total number of shortcuts comparable to the number of original edges.

The asymptotic complexity of CH preprocessing is in the worst-case scenario, since running the contraction for each node, while running the witness search for all of them, might involve search over all edges.
In terms of memory, the CH graph can be estimated as , where is the original edges together with the shortcuts. In practice, can even be smaller than . The witness search significantly reduces the number of added shortcuts. Also, a CH stores each bidirectional edge only once, with forward and backward flags. So on road networks, the CH graph often ends up with fewer edges than the input graph. However, on graphs that do not have a road structure, the contraction can add many more shortcuts, up to , and then the CH graph takes more space than the input.
Bidirectional Dijkstra (Bi-Dijkstra)
Bidirectional Dijkstra is a one-to-one shortest path algorithm, which runs two simultaneous searches: forward from the source and backward from the target . The algorithm terminates when the minimum key across both queues exceeds . In a CH graph, the forward search follows only upward edges from , and the backward search follows only upward edges from . The two frontiers meet at the apex without visiting contracted vertices.
The asymptotic complexity of Bi-Dijkstra over a CH graph is , or with a Fibonacci heap, where includes original edges and inserted shortcuts. Although , the CH query runs much faster than plain Dijkstra in practice. Both searches follow only upward edges and are independent, making them easy to parallelise. Also, the inserted shortcuts let the search move much faster through the graph. On continental road networks, the CH query settles a few hundred to a few thousand vertices, whereas plain Dijkstra settles millions.

Industry deployment. CH is the most deployed algorithm for road routing in production systems. Open-source engines OSRM and GraphHopper both use CH as their primary preprocessing technique. It achieves sub-millisecond queries on continental OpenStreetMap data.
Bucket-CH
Bucket-CH is a modification of CH for one-to-many queries. The algorithm operates in three phases.
The first phase runs standard CH precomputation on . It produces the upward graph and the downward graph .
The second phase operates on the fixed set of targets . For each target , a backward search is run on . Each vertex found by this search stores a tuple in its bucket, where is a distance between and . This phase is offline and performed once per target set.
The third phase answers a query from a source . A forward search is run on . For each vertex settled by this search, its bucket is evaluated. Each entry yields a candidate distance , which updates the tentative distance to if it improves on the best value seen so far. After the forward search finishes, the algorithm computes the shortest-path distance from to every in a single pass.

Preprocessing in Bucket-CH has two parts. The first is a CH build with asymptotic complexity . The second is bucket construction over the target set , costing . Both parts are performed offline. The query then runs a single forward Dijkstra from followed by bucket scans at each settled vertex, with worst-case complexity without a Fibonacci heap, where is the forward search space and is the bucket size at vertex .
Running independent CH queries would cost , the same as bucket construction alone. So for a single one-to-many query against a fresh target set, Bucket-CH offers no advantage. The benefit arises when the target set is fixed, and many queries are issued from different sources against it. The backward searches are performed once during bucket construction and amortised across all subsequent queries.
Regarding memory, Bucket-CH stores the CH search graph and the buckets: . In road networks, the CH search space is small, but with a large target set, the buckets dominate the memory.
Hub Labeling
Hub Labelling (HL) is a one-to-one pathfinding algorithm. It doesn't require any graph search. HL assigns each vertex a forward label and a reverse label . It guarantees that for every pair , the intersection contains a hub on the shortest - path. A query returns without any priority queue or edge relaxations.

The asymptotic complexity of an HL query is the cost of merging two sorted lists: . There is no priority queue, no edge relaxation, and no graph search. If the average label size is , queries run in time. This makes HL queries faster than CH on road networks. On walking networks, the speedup is smaller, since walking graphs have a weaker hierarchical structure. The cost of this improvement is increased preprocessing and storage. Computing optimal labels is NP-hard in general, so HL relies on heuristics built on top of an existing CH. Total storage is , much larger than CH, which stores only . On continental road networks, HL needs an order of magnitude more memory than CH.
The asymptotic complexity of HL precomputation is not estimated in the original paper. However, for the standard pruned, CH-based label construction we estimate it as , where the term reflects the pruning lookup done at each of the label entries.
Public Transit Routing
The speed-up techniques above assume two properties that hold on road networks but break down in public transit.
First, edge weights are typically modelled as static. The travel time on a road segment does not depend on when the driver arrives. Time-dependent extensions of CH exist, but the core preprocessing still assumes smooth, slowly changing cost functions. In a transit network, travel times are discrete functions of departure time determined by the timetable. A passenger who arrives at a stop at 8:01 and one who arrives at 8:29 may wait for different vehicles with different running times.
Second, road networks have a hierarchical structure. Roads have different levels of importance: small local roads, national roads, etc. A typical journey trip moves from the bottom of the hierarchy to the top, then back. Transit networks have no such hierarchy. A cross-city transit journey may require a sequence of local buses and useful intermediate stops.
These differences force transit routing algorithms to operate directly on the timetable.
What a transit query actually asks
Before the algorithms, it's worth pinning down what we're even asking for. The central query type in public transit routing is the earliest arrival query: given a source , a target , and departure time , find a journey minimising arrival time at . A practically important generalisation is the multicriteria query, which asks for all Pareto-optimal journeys with respect to arrival time, number of trips, and potentially additional criteria such as walking duration or fare. Another type of query is range queries, which find an optimal route within a time range.
Time-Dependent Dijkstra
Unlike road networks, where edge weights are typically fixed, public transit networks use edge weights that depend on timetables. For each edge , the arrival time function maps a departure time at to the earliest arrival time at . Time-Dependent Dijkstra (TD-Dijkstra) is a Dijkstra-based one-to-one and one-to-many shortest-path algorithm, which replaces fixed edge costs with arrival time functions evaluated via binary search.

TD-Dijkstra requires the FIFO property, and that is why filtering of the dominated connections should be applied to it.
The asymptotic complexity of TD-Dijkstra without a Fibonacci heap can be estimated as standard Dijkstra plus binary search over the largest connection set across all edges . It will be equal to . The first term is the standard Dijkstra cost on the timetable graph. The second comes from the binary search at each edge relaxation. In memory, TD-Dijkstra is plain Dijkstra plus the timetable: .
A* with the Tung-Chew heuristic
A* works on the transit network too. The catch is the heuristic. Euclidean distance to the target does not work here, because travel time depends on the schedule, not the map. The Tung-Chew heuristic is an option. It came out of a multicriteria Pareto-optimal path algorithm. The idea is simple: we weight every edge by the sum of its criteria, run a search backward from the target, and get the shortest aggregate distance from every node to it.
However, this heuristic is not free, and the cost is all per query. There is no preprocessing, nothing is built once and reused. Building the heuristic is one backward Dijkstra from the target on the reversed graph, and the query itself is an A* search on top of that. Both searches run on the same timetable graph. The total cost is the same order as TD-Dijkstra, and memory is also the same.
RAPTOR and Its Variants
RAPTOR answers single-source earliest-arrival queries to either a fixed target or to all stops simultaneously. In contrast to TD-Dijkstra, it requires the stop-to-stop transfer graph of the public transit network to be transitively closed. The algorithm operates in rounds, where round discovers journeys with exactly trips by extending journeys from round . For each stop and round , the arrival time represents the earliest known arrival at using at most trips. A query from source with departure time initializes and all other arrival times to , then iterates until no improvements occur.

Each round consists of two phases. In the route scanning phase, the algorithm sequentially scans all routes passing through stops improved in the previous round, tracking the earliest boardable trip . At each stop along the route, it checks whether alighting from improves , and whether an earlier trip becomes boardable. In the transfer relaxation phase, the algorithm relaxes all outgoing edges from improved stops, updating whenever for edge .

RAPTOR correctly handles buffer times by applying them only when boarding a new trip, not when continuing on the same trip. This is possible because RAPTOR explicitly tracks trip membership during route scanning.
Algorithm: RAPTOR
Require: Timetable (S, T, R, G) with buffer β(p) at each stop p;
         source p_s; target p_t; departure time τ_dep
Ensure:  Pareto-set of journeys to p_t

τ_k(p) ← ∞ for all p, k;  τ_0(p_s) ← τ_dep;  M ← {p_s}
for k = 1, 2, … do
    if M = ∅ then break
    τ_k(p) ← τ_{k-1}(p) for all p
    Build route queue Q from marked stops;  M ← ∅
    for each (r, p) ∈ Q do
        T_min ← ⊥
        for each stop p_i in r from p onward do
            if T_min ≠ ⊥ and τ_arr(T_min, p_i) < min(τ_k(p_i), τ_k(p_t)) then
                τ_k(p_i) ← τ_arr(T_min, p_i);  M ← M ∪ {p_i}
            τ_board ← τ_{k-1}(p_i) + β(p_i)      # transfer waits the buffer
            t' ← earliest trip of r departing p_i at time ≥ τ_board
            if t' departs earlier than T_min then T_min ← t'
    for each p ∈ M, each (p, p') ∈ G do
        if τ_k(p) + τ_tra(p, p') < τ_k(p') then
            τ_k(p') ← τ_k(p) + τ_tra(p, p');  M ← M ∪ {p'}
return { (τ_k(p_t), k) : τ_k(p_t) < ∞ }
The main algorithmic benefit of RAPTOR is that it avoids using a priority queue. Let denote the number of rounds, the number of stops along route , and the total route length. Each round runs in time, since every route and every trip on it is scanned at most once. Over rounds, the worst-case running time is therefore . In practice, is small, since journeys with many transfers are rare. However, as the transfer distances increase, might grow up to , since RAPTOR requires the transfer graph to be transitively closed.
RAPTOR doesn't require any algorithmic preprocessing, except for data structure precomputation, and by its architecture optimises two criteria: earliest arrival and transfer amount. It makes it a widely deployed transit routing algorithm, powering OpenTripPlanner, R5, Navitia.io, Solari, and many other systems.
We can estimate its memory as , where can reach because of the closure. This estimate is equal for all the following modifications of RAPTOR (rRAPTOR, McRAPTOR, BM-RAPTOR).
rRAPTOR. rRAPTOR is a RAPTOR modification for range queries, answering one-to-one or one-to-many queries. Let be the set of distinct departure times in the query range. rRAPTOR runs one RAPTOR search for each departure time in and returns the union of their Pareto-optimal results, so its query time is .

McRAPTOR. McRAPTOR is a one-to-one and one-to-many extension of RAPTOR, which optimises additional criteria beyond arrival time and number of transfers, such as walking duration. Given a set of criteria, a journey dominates another journey if is not worse than in any criterion.

McRAPTOR replaces each scalar label with a Pareto bag of incomparable journeys, whose size is not bounded and depends on both the chosen criteria and the network characteristics. The blow-up is exponential rather than linear in the number of criteria; Pareto sets become impractically large for three or more criteria. Let be the largest Pareto bag and the number of criteria. Every scan and transfer relaxation becomes a bag merge, each costing , giving an overall bound of . This estimate is only nominal: has no polynomial bound and may grow exponentially in .
BM-RAPTOR. BM-RAPTOR keeps only a restricted Pareto set that drops journeys with bad tradeoffs.

Let be the set of anchor journeys, Pareto-optimal on arrival time and number of trips alone. A single RAPTOR run produces them. With an arrival-time slack and a trip slack , the additive restricted Pareto set is
A multiplicative slack fits passengers better, since a long detour matters more on a long trip than on a short one, relative to the anchor duration :
BM-RAPTOR runs in three phases. First, a forward RAPTOR runs from the source and gives the anchor journeys and the earliest arrival at the target. Second, a backward RAPTOR runs from the target, marking a superset of the stops that can still reach the target inside the slacks. Third, a McRAPTOR phase builds the restricted set, pruning every label round by round against the arrival-slack bound.

Since BM-RAPTOR relies on the forward RAPTOR to the target on the first run, it supports only one-to-one queries. We estimate its complexity as , with the slack-bounded restricted bag in place of the unbounded . The restriction buys nothing asymptotically, but in practice it gives a huge speedup: on large metropolitan networks a four-criteria restricted Pareto set can be computed faster by a factor of up to 65, while retaining the important journeys.
Connection Scan Algorithm
The Connection Scan Algorithm (CSA) is a non-graph-based, one-to-one and one-to-many shortest-path algorithm that answers earliest-arrival-time queries in timetable-based information systems. It merges all schedules into a single array of connections sorted by departure time. It runs a single binary search for the closest connection to the departure time from the source, then sequentially scans through the following valid connections, updating the arrival time for each station. The process stops once it encounters a connection whose departure time exceeds the target station's earliest arrival time. CSA requires the transitive closure of the transfer graph and correctly handles the buffer in the same way as RAPTOR.
Algorithm: Connection Scan Algorithm (CSA)
Require: Connections C sorted by τ_dep; source s; target t; departure time τ_dep
Ensure:  Earliest arrival at t

τ[v] ← ∞ for all v;  τ[s] ← τ_dep;  R[·] ← false
for each c ∈ C in order do
    if τ_dep(c) > τ[t] then break
    if R[T_c] or τ[v_dep(c)] + β(v_dep(c)) ≤ τ_dep(c) then
        R[T_c] ← true
        if τ_arr(c) < τ[v_arr(c)] then
            τ[v_arr(c)] ← τ_arr(c)
            for each footpath f from v_arr(c) do
                τ[f_arr] ← min(τ[f_arr], τ_arr(c) + τ_tra(f))
return τ[t]
CSA runs the search over the sorted list of connections, visiting each connection at most once. This gives a worst-case per-query running time of , where is the total number of connections. Preprocessing is just a single sort of all connections by departure time, . CSA's performance lies in constant-factor efficiency: each connection is processed via a few array lookups rather than priority-queue operations. However, the framework doesn't scale well for multicriteria search; the multicriteria version, MCSA, is significantly slower than McRAPTOR.
CSA stores the sorted connection array and the closed transfer graph: , where can reach up to because of the closure.
Trip-Based Routing (TB)
Trip-Based Routing (TB) is a one-to-one journey planning algorithm. TB uses trips as its fundamental building block. Each trip is labelled with the stops at which it can be boarded. A precomputed list of transfers to other trips is then scanned, and newly reached trips are labelled. When a trip reaches the destination, a journey is added to the result set. Structurally, this is a breadth-first traversal of trip segments connected by a precomputed transfer set . Like RAPTOR, TB operates in rounds, but scans individual trip segments rather than entire routes. In practice, TB outperforms RAPTOR on two-criteria queries (arrival time and number of transfers), at the cost of this preprocessing step.

We estimate the worst-case query as , where is the total number of elementary connections and is the size of the preprocessed transfer set. The size of is reduced by two heuristic rules (U-turn elimination and transfer-replacement reduction) whose effect depends on the network. We estimate the preprocessing cost as , where is the average number of transfer edges per stop and bounds the trips boardable at a stop.
TB requires the transitive closure of the transfer graph and was originally evaluated only for sparse transfer graphs; it does not support unrestricted transfer graphs. A later variant using Condensed Search Trees drops the transitive-closure requirement and reaches microsecond-scale queries, but increases preprocessing overhead by up to an order of magnitude. TB's memory is estimated as .
Transfer Patterns
Transfer Patterns is a one-to-one shortest-path algorithm originally developed at Google for Google Maps, based on the observation that many optimal journeys between a given origin and destination share the same sequence of transfer stops. The technique precomputes, for each pair of stops, the set of transfer stop sequences appearing in optimal journeys, so queries can be answered by searching only within these patterns.
The precomputation is heavy. The original paper estimates the total number of settled labels as , quadratic in the number of stations. Scalable Transfer Patterns reduces it by roughly three orders of magnitude by adding frequency-based profile labels that exploit the timetable's periodicity. We re-express the original estimate as .
A query first assembles the precomputed transfer patterns for the source–target pair into a small directed acyclic query-graph (DAG), then runs a time-dependent multi-criteria Dijkstra search on it. We estimate the query cost as , where is the query-graph size, the Pareto-bag size, and the cost of a single direct-connection query. Crucially, depends only on the pattern count of the queried pair, so query time is independent of network size. The memory can be ; this quadratic storage is the main weakness.
Unlimited Transfer and Multimodal Routing
Public transit algorithms such as CSA, RAPTOR and TB require the transfer graph to be transitively closed, which becomes the primary bottleneck for large transfer radii. Many papers claim that reducing walking distances is beneficial because people usually prefer not to walk long distances, and that it doesn't affect travel time in practice. However, Wagner and Zündorf demonstrated practical applications of long-distance transfer and the fact that fully multimodal paths usually have an earlier arrival time. The median difference during nighttime on the German network was around 2 hours; even during the daytime, 75% of queries with transfer reduction return non-optimal paths. They also showed that limiting walking to 20 minutes already produces a graph too large for practical use, yet removing restrictions substantially reduces travel times.
From here on, every algorithm works with the full transfer graph and drops the transitive-closure requirement — which is exactly what makes unlimited transfers practical.
Core-CH
In multimodal pathfinding, the transfer graph is used only for initial transfers from the source to a boarding stop, intermediate transfers between trips, and final transfers to the target. As a result, at query time, the algorithm doesn't need to search the full transfer graph, only the pairwise distances between stops. Core-CH provides these efficiently by precomputing a small core graph that keeps the stops while contracting away the rest of the transfer graph. It iteratively contracts non-stop vertices in standard CH order. The process stops once the average vertex degree of the core graph crosses a specified threshold.

Core-CH performs the same CH precomputation, but interrupts it when it crosses a specified threshold. Its preprocessing cost is therefore bounded above by full CH, . At query time, it runs the same bidirectional Dijkstra on the augmented graph. This architecture allows us, in practice, to generate longer first and last miles, which might represent longer transfer legs, where the user may take a taxi to the transit network or reach out from it to the target stop.

In memory, Core-CH is the same form as CH: it stores the augmented graph, . Because it stops the contraction once the core gets too dense, it adds fewer shortcuts than a full CH.
MR
MR (originally MR-∞) uses the Core-CH concept in its search and extends RAPTOR by replacing local transfer relaxation with Dijkstra's algorithm on the Core-CH graph. MR initialises the priority queue with all stops marked in the current round, then runs a single multi-source Dijkstra search, settling every reachable core vertex and marking any stop reached. Initial and final transfers are handled separately via upward and downward searches from the source and target vertices.

We estimate MR as standard RAPTOR complexity plus Dijkstra on the core graph : . MR search performs faster than RAPTOR when , meaning the transitive closure becomes too dense and RAPTOR's transfer phase, which scans up to closure edges per round, becomes very slow. MR doesn't require timetable-dependent preprocessing; its total memory is .
MCR
MCR is the multicriteria version of MR. It extends the search to additional criteria beyond arrival time and number of trips, such as walking duration or costs. Its complexity is the same as McRAPTOR, with the transfer search over the transitively closed graph replaced by a Dijkstra run on the core graph : . It stores the same data structure as MR and does not need timetable-dependent preprocessing.
Hub Labelling for Unlimited Transfers
Phan and Viennot applied Hub Labelling to the transfer graph in both RAPTOR and CSA to accelerate unlimited-transfer routing without running a Dijkstra search in each round. They report a speedup over MR on the London dataset for HL-RAPTOR. However, this claim was based solely on copying the number from the MR paper and hasn't been properly tested on the same machine with the same query set. This gap was later addressed in the literature, showing that the actual performance is much lower.
We estimate the per-round transfer phase of HL-RAPTOR as in the worst case, giving . The analogous bound for HL-CSA is . HL-RAPTOR is faster than RAPTOR when , which is valid for the unlimited transfer problem. In memory, HL-RAPTOR is and HL-CSA is .
ULTRA
Stop-level shortcuts
ULTRA is, for now, the main state-of-the-art framework for unlimited transfers. Rather than computing the full transitive closure, ULTRA precomputes only the shortcut edges representing transfers in Pareto-optimal journeys. For initial and final transfers, ULTRA uses Bucket-CH one-to-many searches across the full street network, which significantly accelerates the search process.

For each source stop , ULTRA runs rRAPTOR restricted to two rounds (canonical MR), with transfers relaxed by Dijkstra on a contracted core graph . The total complexity of ULTRA preprocessing is .
In practice, the original paper reports preprocessing times of roughly 9 minutes for Switzerland and around 8 hours for Germany. The preprocessing is performed once per timetable and amortised across all subsequent queries. This makes ULTRA unsuitable for online use where the timetable changes frequently. These shortcuts are timetable-dependent; independently of them, ULTRA builds a Bucket-CH for the initial and final transfers that remains valid across schedule changes. Combined with Bucket-CH, classical algorithms like CSA and RAPTOR can run on these shortcuts to find multimodal paths, achieving up to a speedup over MR and HL-RAPTOR.
In memory, ULTRA stores the stop-level shortcut set and the Bucket-CH: .
Multicriteria stop-level shortcuts
With unlimited transfers, optimising only arrival time and the number of trips is not enough. A journey optimal on those two criteria can spend a long time walking, while a journey arriving slightly later walks far less. McULTRA is a three-criteria extension of ULTRA that adds transfer time as a third criterion. The shortcut computation keeps the ULTRA structure, but enumerates journeys with McRAPTOR instead of RAPTOR and relaxes transfers with a multi-criteria Dijkstra.
By adding the third criterion, the number of stop-level shortcuts grows less than a factor of two, and the preprocessing time is roughly two to four times slower than two-criterion ULTRA. For comparison, three-criterion MCR is about twenty times slower than MR, meaning the shortcut approach scales much better. We call the version that runs on multicriteria shortcuts ULTRA-McRAPTOR, and the bounded variant UBM-RAPTOR. We estimate the shortcut precomputation by adding an factor on top of stop-level ULTRA. In memory, it has the same form as stop-level ULTRA.
Event-level shortcuts
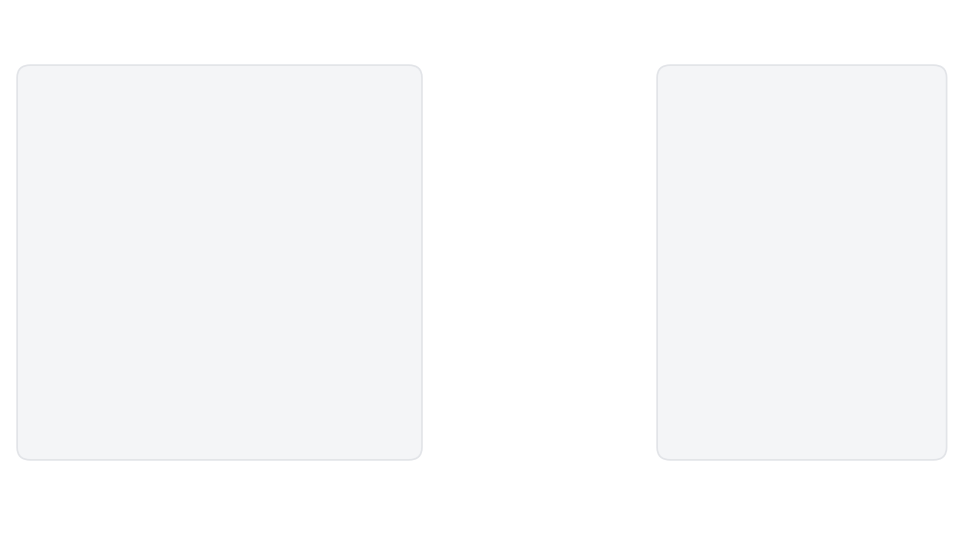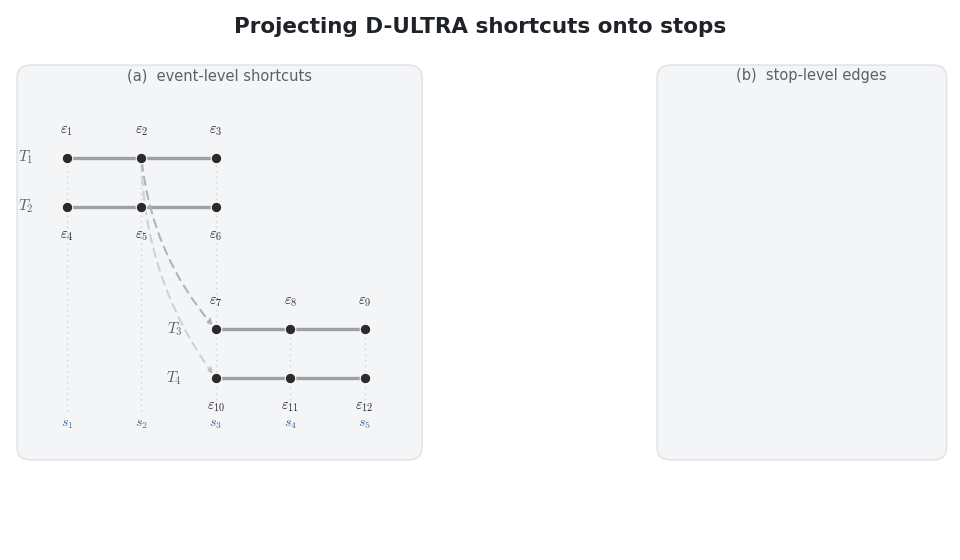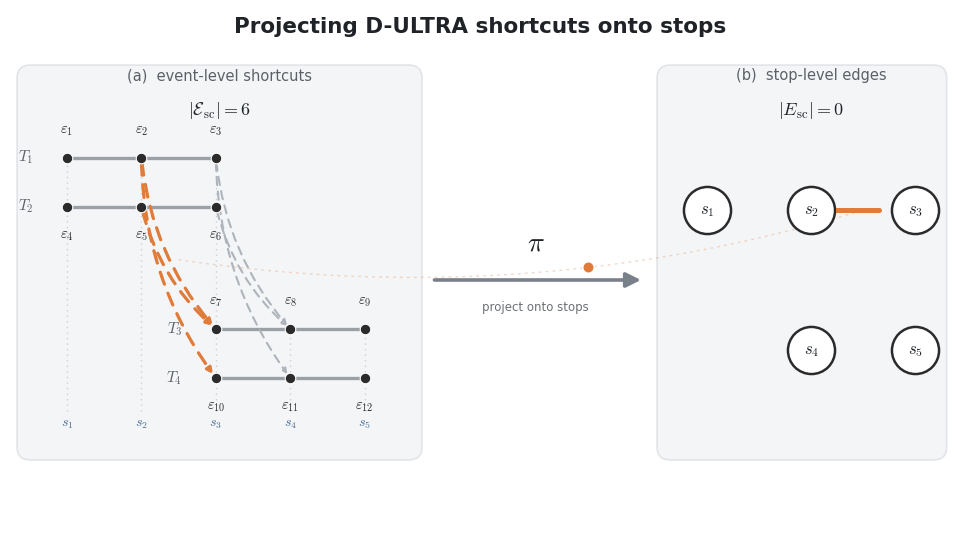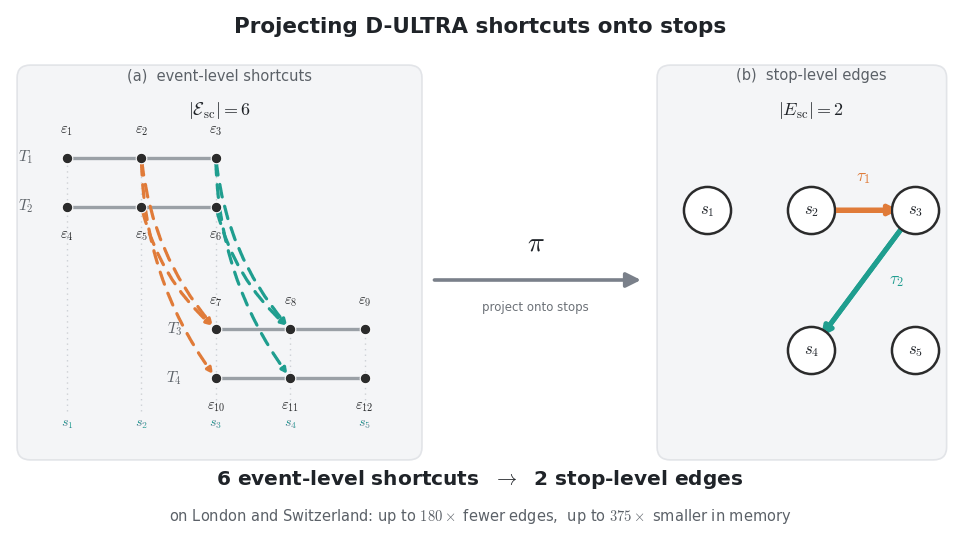
An alternative version of ULTRA was developed for TB. Since TB indexes transfers between stop events rather than between stops, the ULTRA preprocessing was adapted to produce event-level shortcuts. The adaptation keeps the ULTRA journey enumeration but produces time-dependent shortcuts under strict domination. We estimate its asymptotic complexity as the same as stop-level ULTRA, differing only in constant factors and in the output, which is the larger event-level shortcut set . With TB on top, the memory usage is .
Delay-ULTRA
Algorithms without timetable-dependent preprocessing, like MR, HL-RAPTOR, and HL-CSA, are inherently delay-robust. The ULTRA framework uses timetable information in its preprocessing step and, as a result, is not robust to delays.
DB-ULTRA introduced unannotated stop-level shortcuts valid for any delay scenario within a fixed buffer . The shortcut count grows rapidly under the Delay-All model (over twelve million at min on Switzerland), which motivated annotating shortcuts with delay sub-intervals and adapting the framework to TB. D-ULTRA computes shortcuts at the event level: each shortcut connects two specific stop events and carries a delay interval. This granularity is natural for TB, which indexes transfers by stop event, but it is incompatible with CSA and RAPTOR, which index transfers by stop.

The offline computation is basically the ULTRA enumeration, run in best-case delay scenarios, splitting the work by origin stop prefix and running two witness searches per subproblem instead of one. We estimate its complexity as the same as ULTRA preprocessing; the only differences are a constant factor and the output, which is the event-level shortcut set with a delay interval attached to each shortcut. With TB on top, the total memory is .
So which one should you use?
We've covered a lot of ground — three worlds, really: road network routing, public transit routing, and multimodal routing with unrestricted transfers. There's no single winner. Each makes different assumptions about the input, and the right pick is always a trade-off among preprocessing cost, query speed, and how well it copes with a timetable that keeps changing under you.
Road network algorithms exploit hierarchy and static edge weights to enable sub-millisecond query times on continental graphs. Contraction Hierarchies and Hub Labelling are the main state-of-the-art solutions, with HL trading additional memory for the fastest query times. Bucket-CH extends CH to one-to-many queries, which is useful in multimodal routing.
Public transit algorithms operate directly on the timetable. CSA provides the fastest earliest-arrival query response with the minimum preprocessing cost. RAPTOR is a good choice for multicriteria search and needs no preprocessing beyond data-structure construction. TB outperforms RAPTOR on multi-criteria queries but requires preprocessing. Transfer Patterns push this trade-off further, achieving microsecond query times through heavy precomputation. CSA, RAPTOR, and TB require a transitively closed transfer graph, which makes them hard to scale to multimodal pathfinding over arbitrary transfer distances.
The unlimited-transfer setting splits into two families. The first (MR, HL-RAPTOR, HL-CSA) preprocesses only the transfer graph and therefore remains valid across timetable changes and delays. The second (ULTRA) precomputes shortcuts that depend on the schedule. It achieves the fastest query times among unlimited-transfer algorithms, but may lose validity when the schedule changes. Delay-ULTRA partially addresses this by precalculating the needed shortcuts within a constant delay and adding an online update phase, but it can't guarantee solution optimality.
If you want the whole picture on one screen, here are the two cheat-sheets — what each algorithm stores, and how fast it answers. (All the memory and preprocessing bounds below are our own estimates; most of the original papers never state one.)
Stored data-structure memory
| Algorithm | Preprocessing time | Closure | Memory (data structure) |
|---|---|---|---|
| Dijkstra | none | no | |
| A* | none | no | |
| Bi-Dijkstra (CH) | no | ||
| Bucket-CH | no | ||
| Hub Labelling | no | ||
| TD-Dijkstra | — | no | |
| A* (Tung-Chew) | — | no | |
| RAPTOR | — | yes | |
| rRAPTOR | — | yes | |
| McRAPTOR | — | yes | |
| BM-RAPTOR | — | yes | |
| CSA | yes | ||
| TB | yes | ||
| Transfer Patterns | labels | no | |
| MR | Core-CH | no | |
| MCR | Core-CH | no | |
| HL-RAPTOR | HL | no | |
| HL-CSA | CSA + HL | no | |
| ULTRA-RAPTOR | ULTRA (stop) + Core-CH + Bucket-CH | no | |
| ULTRA-CSA | ULTRA (stop) + Core-CH + Bucket-CH | no | |
| ULTRA-TB | ULTRA (event) + Core-CH + Bucket-CH | no | |
| ULTRA-McRAPTOR | McULTRA (stop) + Core-CH + Bucket-CH | no | |
| UBM-RAPTOR | McULTRA (stop) + Core-CH + Bucket-CH | no | |
| Delay-ULTRA-TB | Delay-ULTRA + Core-CH + Bucket-CH | no |
Memory bounds are our estimates; none of the original papers state one. These bounds count only what each algorithm keeps in memory between queries; per-query working memory is excluded.
Query algorithms and query-time complexity
| Algorithm | Problem | Criteria | Query type | Query time | Stable |
|---|---|---|---|---|---|
| Dijkstra | road | generalized cost | 1-to-1 / 1-to- | — | |
| A* | road | generalized cost | 1-to-1 | — | |
| Bi-Dijkstra (CH) | road | generalized cost | 1-to-1 | — | |
| Bucket-CH | road | generalized cost | 1-to- | — | |
| Hub Labelling | road | generalized cost | 1-to-1 | — | |
| TD-Dijkstra | transit | 1-to-1 / 1-to- | yes | ||
| A* (Tung-Chew) | transit | generalized cost | 1-to-1 | yes | |
| RAPTOR | transit | 1-to-1 / 1-to- | yes | ||
| rRAPTOR | transit | , range | 1-to-1 / 1-to- | yes | |
| McRAPTOR | transit | , ext. | 1-to-1 / 1-to- | yes | |
| BM-RAPTOR | transit | , ext., bnd. | 1-to-1 | yes | |
| CSA | transit | 1-to-1 / 1-to- | re-sort | ||
| TB | transit | 1-to-1 | no | ||
| Transfer Patterns | transit | 1-to-1 | no | ||
| MR | multimodal | 1-to-1 / 1-to- | yes | ||
| MCR | multimodal | , ext. | 1-to-1 / 1-to- | yes | |
| HL-RAPTOR | multimodal | 1-to-1 / 1-to- | yes | ||
| HL-CSA | multimodal | 1-to-1 / 1-to- | yes | ||
| ULTRA-RAPTOR | multimodal | 1-to-1 / 1-to- | no | ||
| ULTRA-CSA | multimodal | 1-to-1 / 1-to- | no | ||
| ULTRA-TB | multimodal | 1-to-1 | no | ||
| ULTRA-McRAPTOR | multimodal | , ext. | 1-to-1 / 1-to- | no | |
| UBM-RAPTOR | multimodal | , ext., bnd. | 1-to-1 | no | |
| Delay-ULTRA-TB | multimodal | 1-to-1 | partial |
"Query type" is 1-to-1, 1-to-, or both; "Stable" is validity under timetable changes. Fibonacci-heap variants reduce terms to . ; "ext." = extra criteria, "bnd." = bounded variant.
References
- Dijkstra, Edsger W.. A Note on Two Problems in Connexion with Graphs. Numerische Mathematik, 1959.
- Fredman, Michael L., Tarjan, Robert Endre. Fibonacci heaps and their uses in improved network optimization algorithms. J. ACM, 1987.
- Hart, Peter E., Nilsson, Nils J., Raphael, Bertram. A Formal Basis for the Heuristic Determination of Minimum Cost Paths. IEEE Transactions on Systems Science and Cybernetics, 1968.
- Goldberg, Andrew V., Werneck, Renato F.. Computing Point-to-Point Shortest Paths from External Memory. Proceedings of the 7th Workshop on Algorithm Engineering and Experiments (ALENEX'05).
- Sanders, Peter, Schultes, Dominik. Highway Hierarchies Hasten Exact Shortest Path Queries. Algorithms – ESA 2005.
- Geisberger, Robert, Sanders, Peter, Schultes, Dominik, Vetter, Christian. Exact Routing in Large Road Networks Using Contraction Hierarchies. Transportation Science, 2012.
- Geisberger, Robert, Sanders, Peter, Schultes, Dominik, Delling, Daniel. Contraction Hierarchies: Faster and Simpler Hierarchical Routing in Road Networks. Experimental Algorithms, 2008.
- Knopp, Sebastian, Sanders, Peter, Schultes, Dominik, Schulz, Frank, Wagner, Dorothea. Computing Many-to-Many Shortest Paths Using Highway Hierarchies. Proceedings of the 9th Workshop on Algorithm Engineering and Experiments (ALENEX'07), 2007.
- Abraham, Ittai, Delling, Daniel, Goldberg, Andrew V., Werneck, Renato F.. A Hub-Based Labeling Algorithm for Shortest Paths in Road Networks. Experimental Algorithms (SEA 2011).
- Bast, Hannah, Delling, Daniel, Goldberg, Andrew, Müller-Hannemann, Matthias, Pajor, Thomas, Sanders, Peter, Wagner, Dorothea, Werneck, Renato F.. Route Planning in Transportation Networks. Algorithm Engineering: Selected Results and Surveys, 2016.
- Bast, Hannah. Car or Public Transport—Two Worlds. Efficient Algorithms: Essays Dedicated to Kurt Mehlhorn on the Occasion of His 60th Birthday, 2009.
- Batz, Gernot Veit, Geisberger, Robert, Sanders, Peter, Vetter, Christian. Minimum Time-Dependent Travel Times with Contraction Hierarchies. ACM Journal of Experimental Algorithmics, 2013.
- Evangelia Pyrga, Frank Schulz, Dorothea Wagner, Christos Zaroliagis. Efficient Models for Timetable Information in Public Transportation Systems. ACM Journal of Experimental Algorithmics, 2008.
- Gerth Stølting Brodal, Riko Jacob. Time-dependent networks as models to achieve fast exact time-table queries. Electronic Notes in Theoretical Computer Science, 2003.
- Tung, Chi Tung, Chew, Kim Lin. A multicriteria Pareto-optimal path algorithm. European Journal of Operational Research, 1992.
- Daniel Delling, Thomas Pajor, Renato F. Werneck. Round-Based Public Transit Routing. Proceedings of the 14th Meeting on Algorithm Engineering and Experiments (ALENEX), 2012.
- Delling, Daniel, Dibbelt, Julian, Pajor, Thomas. Fast and Exact Public Transit Routing with Restricted Pareto Sets. Proceedings of the 21st Workshop on Algorithm Engineering and Experiments (ALENEX'19), 2019.
- Julian Dibbelt, Thomas Pajor, Ben Strasser, Dorothea Wagner. Connection Scan Algorithm. ACM Journal of Experimental Algorithmics, 2018.
- Sascha Witt. Trip-Based Public Transit Routing. Algorithms — ESA 2015, 2015.
- Agarwal, Prateek, Rambha, Tarun. Scalable Algorithms for Bicriterion Trip-Based Transit Routing. IEEE Transactions on Intelligent Transportation Systems, 2024.
- Witt, Sascha. Trip-Based Public Transit Routing Using Condensed Search Trees. 16th Workshop on Algorithmic Approaches for Transportation Modelling, Optimization, and Systems (ATMOS 2016), 2016.
- H. Bast, E. Carlsson, A. Eigenwillig, R. Geisberger, C. Harrelson, V. Raychev, F. Viger. Fast Routing in Very Large Public Transportation Networks Using Transfer Patterns. ESA 2010, 2010.
- Bast, Hannah, Hertel, Matthias, Storandt, Sabine. Scalable Transfer Patterns. Proceedings of the Eighteenth Workshop on Algorithm Engineering and Experiments (ALENEX), 2016.
- Bast, Hannah, Storandt, Sabine. Frequency-Based Search for Public Transit. Proceedings of the 22nd ACM SIGSPATIAL International Conference on Advances in Geographic Information Systems.
- Wagner, Dorothea, Zündorf, Tobias. Public Transit Routing with Unrestricted Walking. 17th Workshop on Algorithmic Approaches for Transportation Modelling, Optimization, and Systems (ATMOS 2017), 2017.
- Dibbelt, Julian, Pajor, Thomas, Wagner, Dorothea. User-Constrained Multi-Modal Route Planning. Proceedings of the 14th Workshop on Algorithm Engineering and Experiments (ALENEX).
- Delling, Daniel, Dibbelt, Julian, Pajor, Thomas, Wagner, Dorothea, Werneck, Renato F.. Computing Multimodal Journeys in Practice. Proceedings of the 12th International Symposium on Experimental Algorithms (SEA'13), 2013.
- Duc-Minh Phan, Laurent Viennot. Fast Public Transit Routing with Unrestricted Walking Through Hub Labeling. Analysis of Experimental Algorithms – Special Event, SEA² 2019, 2019.
- Baum, Moritz, Buchhold, Valentin, Sauer, Jonas, Wagner, Dorothea, Zündorf, Tobias. UnLimited TRAnsfers for Multi-Modal Route Planning: An Efficient Solution. Proceedings of the 27th Annual European Symposium on Algorithms (ESA'19), 2019.
- Moritz Potthoff, Jonas Sauer. Fast Multimodal Journey Planning for Three Criteria. 2022 Proceedings of the Symposium on Algorithm Engineering and Experiments (ALENEX), 2002.
- Sauer, Jonas, Wagner, Dorothea, Zündorf, Tobias. Integrating ULTRA and Trip-Based Routing. 20th Symposium on Algorithmic Approaches for Transportation Modelling, Optimization, and Systems (ATMOS 2020), 2020.
- Bez, Dominik. UnLimited TRAnsfer Shortcuts with Delay Tolerance for Multi-Modal Journey Planning. Karlsruhe Institute of Technology, 2020.
- Bez, Dominik, Sauer, Jonas. Fast and Delay-Robust Multimodal Journey Planning. Proceedings of the 26th Workshop on Algorithm Engineering and Experiments (ALENEX'24), 2024.
- Sauer, Jonas. Closing the Performance Gap Between Multimodal and Public Transit Journey Planning. Karlsruhe Institute of Technology (KIT), 2024.