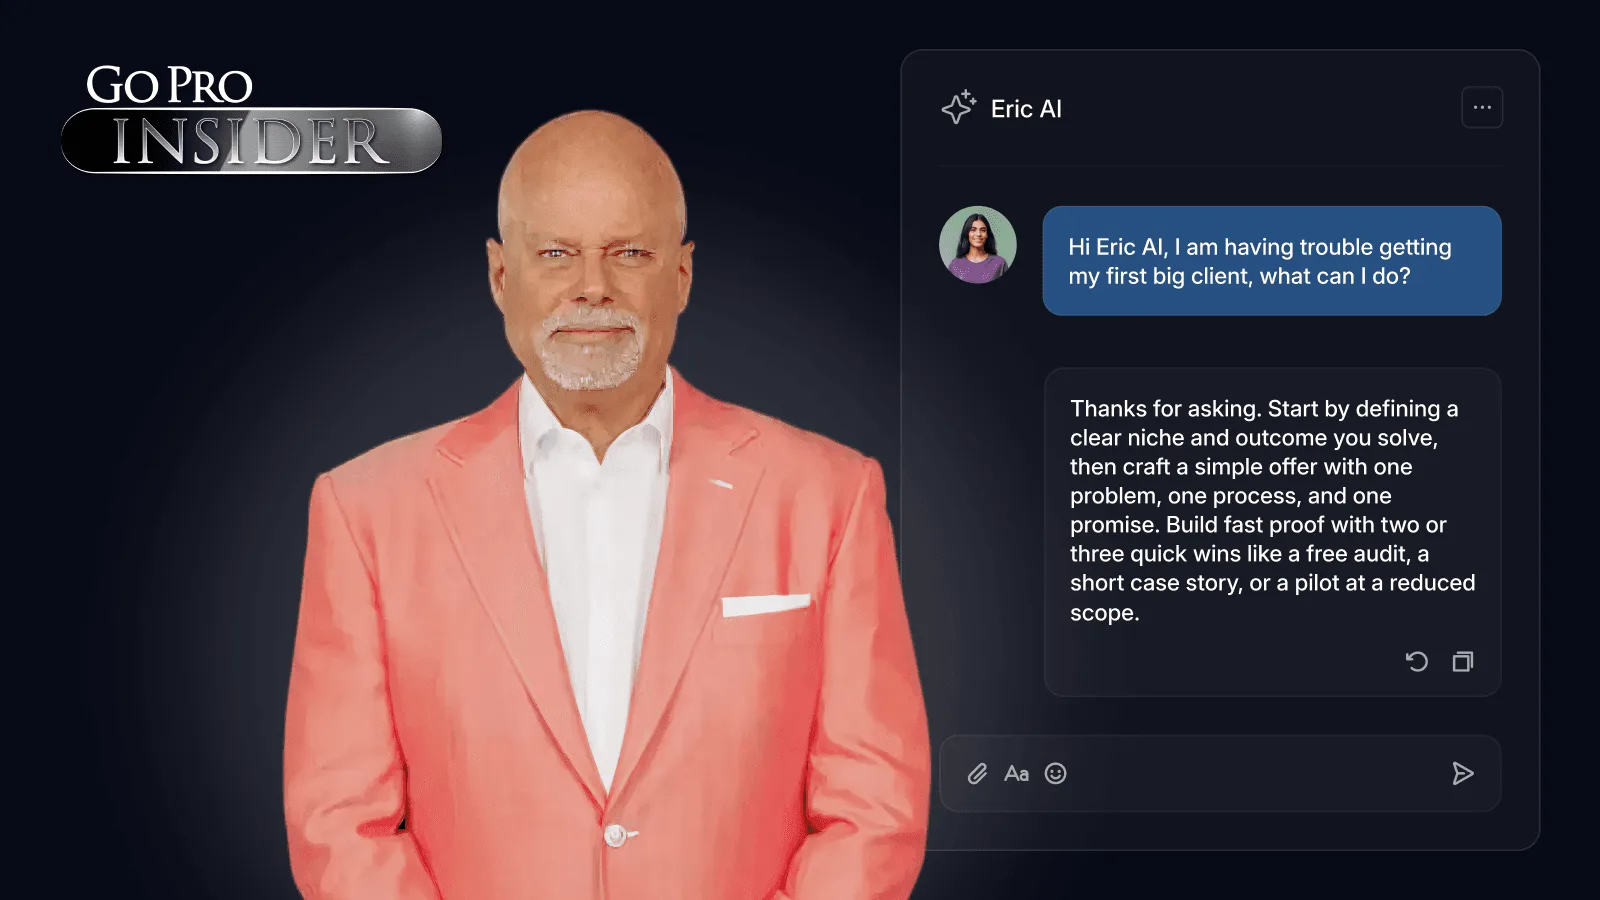
Eric AI: a real-time avatar chatbot built on RAG
We built the backend for Eric AI: a conversational avatar that answers from private knowledge with retrieval-augmented generation and speaks through lip-synced, real-time video — launched on time.
- Industry
- Network marketing
- Services
- Backend development, RAG engineering, Cloud deployment
- Duration
- 4 weeks
- Project duration
- 4 weeks
- Specialists on the team
- 3
- Lip-synced avatar video
- Real-time
Intro
The goal was a conversational AI avatar that answers from private knowledge, stays transparent about its sources and integrates cleanly with the client’s systems.
We prototyped locally, deployed to the cloud early and ran several refinement cycles in close collaboration with the client’s frontend and engineering teams.
Goals and challenges
- 01
Retrieval quality
Chunking and retrieval parameters had to be tuned so answers come only from the provided context.
- 02
Latency and cost
End-to-end latency and token usage had to stay low, with cost control and observability built in.
- 03
Conversation and safety
Multi-turn context, avatar safety and brand alignment all had to hold up in real conversations.
Solution
The backend retrieves answers with RAG, keeps multi-turn context, generates real-time talking-avatar video, runs cloud-natively, integrates with the client’s systems and supports multiple languages.
Conversational RAG service
A FastAPI service with a vector database returns grounded LLM answers and keeps short-term memory through summarization.
Video avatar generation
Lip-synced video streams in real time through a third-party provider.
Cloud-native deployment
Everything runs on Google Cloud Run with autoscaling and HTTP APIs, with monitoring endpoints and documentation for the API, deployment and operations.
Team
- 1 Lead Data Scientist
- 1 Data Scientist
- 1 Backend Developer
Results
- An end-to-end RAG backend with grounded, auditable responses.
- Real-time AI avatar video streaming.
- Deterministic ingestion that cleans, chunks, embeds and indexes documents.
- Optimized LLM usage, safety guardrails and an LLM translation layer.
- Frontend integration support with clear API contracts for streaming.
- The client launched the video avatar on time, with weekly meetings and stand-ups throughout.
What’s next
Next steps include persistent conversation history, broader multilingual support, automated re-indexing, deeper RAG quality work, and optional Vertex AI and voice input.
Thanks to Postdata’s work, the client launched their video avatar on time. The team conducted weekly meetings and stand-ups to ensure effective collaboration throughout the engagement.
Project details
- Client
- Network Marketing Pro
- Industry
- Network marketing
- Services
- Backend development, RAG engineering, Cloud deployment
- Technologies
- Python
- FastAPI
- Gemini
- Pinecone
- HeyGen
- Google Cloud Run
- Team
- 3 — 1 lead data scientist, 1 data scientist, 1 backend developer
- Duration
- 4 weeks